How SMILE works
SMILE · XWhy explainer
Suppose an image classifier labels one picture as a dog. You can ask whether its decision depended on the animal, the background, or some other part of the image. SMILE starts with this one input and investigates what the model does when meaningful parts of it are changed nearby.
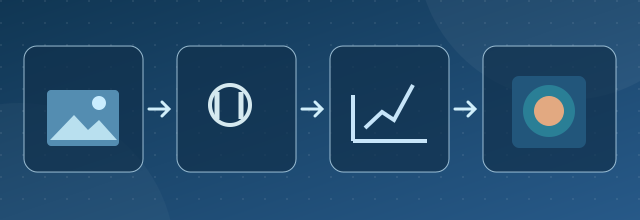
The explanation in four steps
- Create controlled variations. Change selected image regions, words or other features while retaining enough of the original example to study its neighbourhood.
- Observe the model. Run those variations through the model and record how the relevant output changes.
- Measure closeness and fit a local model. Weight the observations according to a suitable distance or similarity measure, then fit a simpler model around the selected input.
- Inspect contributions. The local model estimates which components are associated with the observed changes. Its accuracy in approximating the collected outputs gives an initial indication of how much to trust those estimates.
SMILE uses statistical distance measures in its weighting and comparison steps. The suitable measure depends on whether the outputs are class scores, generated images or text. A distance appropriate for one task should not be assumed to work for another.
A useful result has limits
If a highlighted region changes an image classification under several sensible perturbations, that is stronger evidence about the model's local behaviour than a single coloured heatmap. Yet an explanation of one image does not describe all images. The local model can also fit badly or change when the perturbation scheme changes.
When the result matters, report the model and data version, the chosen input, how variants were produced, the distance and surrogate settings, and the quality of the local fit. Repeat the analysis with small input changes and alternative perturbation settings.
Continue with the technical explanation of SMILE or the foundational paper.